从 1 月 1 日起,任何调用 Perspective 的内容审核流程都将失效。Google 的 Jigsaw 部门将于 12 月 31 日关闭该服务,这标志着用于给在线评论打“毒性”分的最广泛使用工具之一走向终结。对于构建在其之上的平台、发行商、市场和社区而言,未来几个月将面临一个不得不做的决定:迅速寻找替代方案。
Starting January 1, any moderation pipeline calling Perspective will fail. Google’s Jigsaw unit shuts the service down on December 31, ending one of the most widely used tools for scoring online comments for toxicity. For platforms, publishers, marketplaces, and communities built on it, the next few months bring an unwelcome decision. Find a replacement, and fast.
Hindsight 想要成为那个替代者。但它并非推销常规的供应商更换,而是提供了一项迄今为止没有任何 AI 内容审核供应商提供过的东西——针对其模型漏判内容所造成危害的专业担保。
Hindsight wants to be that replacement. But rather than pitching a standard vendor swap, it is offering something no AI content moderation vendor has offered before, a professional guarantee against harm caused by content its model misses.
“隐语是新的侮辱性用语,但要持续稳定地捕捉它难得离谱,”Hindsight 创始人 Dean Gebert 说。“像样地换个模型或工具,不过是把 Perspective 的盲区转移给另一家供应商而已。”被迫迁移兼作企业级审计大多数公司会把 Perspective 的关闭视为一张例行的工程工单。Hindsight 却将其视为一个提出更艰难问题的契机:旧工具最初到底有没有提供准确的防护?
“Coded Language is the new slur, but it’s ridiculously hard to catch consistently,” said Dean Gebert, Hindsight’s Founder. “And a like-for-like model or tool swap just moves Perspective’s blind spots to a different vendor.”Forced Migration Doubles as an Enterprise Audit Most companies will treat Perspective’s shutdown as a routine engineering ticket. Hindsight sees it as a chance to ask a harder question: was the old tool delivering accurate protection in the first place?
Perspective 给评论在表层“听起来”有多毒打分。这对显而易见的侮辱效果很好,但对故意伪装成无害的语言效果很差。
Perspective scores how toxic a comment “sounds” on the surface. That works well on obvious insults. It works poorly on language designed to look harmless.
不法分子清楚这一点,因此他们转向了隐语:诸如“1488”这样的数字代码、“boogaloo”这类极端主义俚语、字符替换(称为“l33tspe@k”)、以及模仿侮辱性词汇发音的拼写错误,如“phag”。成本与责任体现在论坛、帖子、评论、简介、私信、印刷材料等各个场景中。
Bad actors know this, which is why they’ve shifted to Coded Language: numeric codes like “1488,” extremist slang like “boogaloo,” swapped characters (called “l33tspe@k”), and misspellings that mimic a slur’s phonetic sound like “phag“. The cost and liability show up in forums, posts, comments, bios, DMs, printed material, and more.
这也不局限于英语。即使是仅面向美国的平台,也会有西班牙语和其他几十种语言的帖子,因此隐语会随之而来。Hindsight 在 110 种语言上进行了预训练,意味着它能在所有这些语言中追踪隐语,而无需为每种语言单独训练模型。
And it isn’t limited to English. Even a US-only platform has posts in Spanish and dozens of other languages, so Coded Language travels with them. Hindsight was pre-trained on 110 languages, meaning it can follow Coded Language across all of them without a separate model for each language.
利害关系非常严重。根据反诽谤联盟(Anti-Defamation League)的调查,从2016年到2022年中期,极端分子通过324次众筹活动至少筹集了620万美元。此外,还有超过30起针对某大型游戏平台的联邦诉讼指控该平台的监管机制未能有效保护未成年用户。最后,带有白人至上主义内容的商品仍然在各大在线市场上销售。
The stakes are real. From 2016 to mid-2022, the Anti-Defamation League found that extremists raised at least $6.2 million across 324 crowdfunding campaigns. Also, more than 30 federal cases against a major gaming platform allege that its safeguards failed young users. And finally, merchandise with white nationalist messaging still appears on major online marketplaces.
这些问题的背后,其实都存在本应正常运作的监管系统。如今,“Perspective”平台的关闭为人们提供了一个重新思考这些问题的机会。
Behind each of these was a moderation system that was supposed to be working.
为什么二进制模型(binary models)总是被迫做出妥协?许多监管工具都依赖于严格的二进制逻辑(即内容被简单地划分为“安全”或“不安全”两类)。这种逻辑对平台管理者来说是一个两难的局面:如果将监管系统设置得过于严格,系统会频繁向人工审核员发送关于日常俚语的错误警报;如果设置得过于宽松,就会遗漏那些可能引发法律问题的内容。
Perspective’s shutdown creates the opportunity for a rethink. Why Binary Models Are Forced into a Compromise Many moderation tools rely on rigid binary logic: Safe or Unsafe. That creates a lose-lose trade-off for platform executives. Tune the system to be strict, and it floods human reviewers with false alarms on everyday slang.
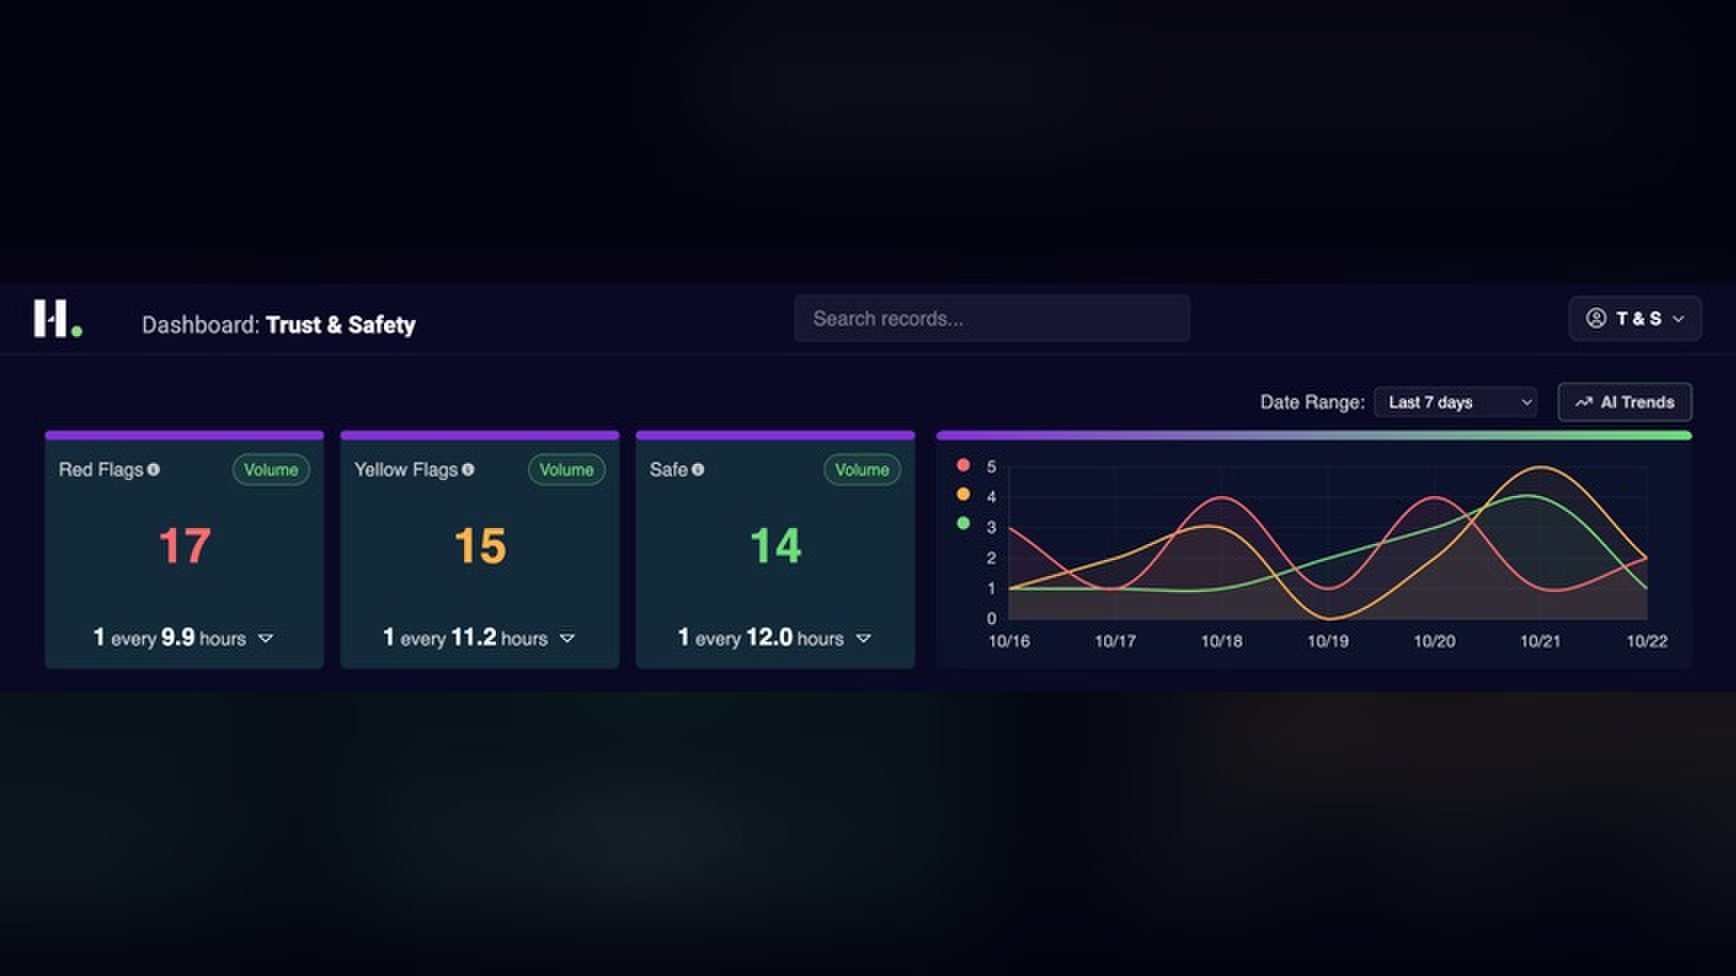
目前常用的分类系统(如“红旗”(Red Flag)、“黄旗”(Yellow Flag)和“安全”(Safe)三类标签),其实难以准确处理那些含义模糊、需要结合具体语境来判断的内容。自动化系统可以快速处理那些显而易见的问题,从而让人工审核员有更多时间去处理那些复杂、难以判断的案例。
Tune it to be lenient, and it misses the content that creates liability. Hindsight’s 3 classes, Red Flag, Yellow Flag, and Safe, create a middle lane for ambiguous, context-dependent language. Automation clears the easy cases, allowing human reviewers to spend time on the harder edge cases (which go back into fine-tuning that client’s instance).
Gebert承认这类讨论可能会让人感到不适,但他举的“最典型的例子”是单词“bitch”:这个词在不同语境下可能带有贬义,也可能表示赞美。如果是对某人发怒时使用的(“这个贱人是谁?”),这显然属于“红旗”(即危险内容);但如果是在朋友之间使用的(“她是我认识的最厉害的人”),则可能属于“安全”内容。然而,二进制模型仍然无法区分这两种情况。
Gebert acknowledges these conversations can be uncomfortable, so his “safest example” is the word bitch, which can be derogatory or adoring depending on context. Aimed at a person in anger (who the hell is this bitch?), it’s a clear Red Flag. Between friends (she’s the baddest bitch I know), it’s likely Safe. But a binary model still can’t tell these apart.
“始终将语境文本准确归类到‘黄旗’类别极其痛苦,”Gebert 笑着说。“这需要同等份量的执着、倔强和拿铁咖啡。但这能让客户减少对人工审核的依赖,获得更准确的结果,所以值得。”基准测试显示什么Hindsight 选取 2205 条真实在线帖子组成固定测试集,由人工分别标注为“红旗”“黄旗”或“安全”,并对 9 款 AI 内容审核模型(Mistral、OpenAI、Meta、Azure、AWS 及其他)进行了基准测试;Hindsight 的模型变体在开发和训练期间从未见过这些帖子。
“Consistently sorting contextual text into an accurate Yellow Flag category was extremely painful,” Gebert laughs. “It took equal doses of obsession, stubbornness, and lattes. But it’ll let clients rely less on human oversight and get more accurate results, so it’ll pay off.”What the Benchmarks Show Hindsight benchmarked 9 AI content moderation models (Mistral, OpenAI, Meta, Azure, AWS, and others) against a fixed set of 2,205 real online posts. A human labeled each as Red Flag, Yellow Flag, or Safe, and Hindsight’s model variants never saw any of the posts during development or training.
在“隐语”检测上,Hindsight 检出率达 97.9%。其他模型得分均在 65% 及以下。其漏报率为 3.3%,误报率为 8.2%。公司在官网公布了完整的基准测试方法论与结果,并支持企业用自有数据测试 Hindsight。专业化的效率:狙击手对决散弹枪这一结果直接挑战了“模型越大效果越好”的假设。Hindsight 不使用单一的大型通用基座模型,而是基于 3 个参数量均不足 6 亿的专用基座模型构建,公司称其表现超越了参数量大达其 14 倍的模型。Gebert 形容这是“更像狙击手,少像散弹枪”。
On Coded Language, Hindsight detected 97.9% of cases. Other models scored 65% and below. Its Missed Flag rate was 3.3% and its False Alarm rate was 8.2%. The company publishes the full benchmark methodology and results on its website, with the ability for companies to test Hindsight with their data. The Efficiency of Specialization: Sniper vs. Shotgun The result is a direct challenge to the assumption that larger models always perform better. Hindsight does not use 1 large, general-purpose base model. It builds on 3 specialized base models, each with fewer than 600 million parameters, and the company says the result outperforms models up to 14 times its size. Gebert calls it more sniper, less shotgun.
其训练数据刻意保持窄域,共 83 MB 真实在线帖子,取自 18 个数据集(约相当于 37 本《哈利·波特》的文本量),包含 29.2 万条经人工标注的帖子。在 164 个训练变体中,公司追踪各变体表现并将最优变体提升为“冠军”版本。100 万美元担保改变了什么企业级 AI 内容审核通常作为成本中心出售。它能降低风险,但鲜有供应商承诺结果担保。
Its training data is intentionally narrow, with 83 MB of real online posts, drawn from 18 datasets (roughly 37 Harry Potter books), including 292,000 posts labeled by human reviewers. Across 164 trained variants, the company tracked how each performed and promoted the best variant to Champion. What a $1M Guarantee Changes Enterprise AI content moderation is typically sold as a cost center. It reduces risk, but few vendors guarantee an outcome.
Hindsight 改变了这一点。若其模型将某帖子判定为“安全”,而该帖子随后引发有据可查的责任事件,客户可获得高达 100 万美元的资金支持,而非仅收到一纸道歉和一个补丁。
Hindsight changes that. If its model labels a post as Safe and that post causes a documented liability event, the client has up to $1 million in financial support, instead of an apology and a patch.
对于面临截止日期的团队来说,实际的做法很简单。替换 Perspective 只需一次 API 调用,而 Hindsight 能捕捉到类似工具从未能够识别的编码语言。
For teams facing the deadline, the practical pitch is simple. Replacing Perspective takes a single API call, and Hindsight catches the Coded Language that similar tools were never built to see.
Gebert 建议的路径是让 Hindsight 与 Perspective 并行运行一周,然后查看它们意见不一致的差异。那些分歧显示仅凭毒性评分可能不足以覆盖的情况。
Gebert’s suggested path is to run Hindsight and Perspective side by side for a week, then look at the delta where they disagreed. Those disagreements show where a toxicity score alone may have been falling short.
Hindsight 将其首批发布的客户数量限制在 4 家商业客户,以便针对每个平台独特的社区政策和风险概况对模型实例进行定制校准。创始人定价将提供给这第一批客户。
Hindsight is capping its launch cohort at 4 commercial clients to allow custom calibration of model instances against each platform’s unique community policies and risk profile. Founder pricing will be offered to that first group.
如需加入发布名单并使用您的数据测试 Hindsight,请访问
To join the launch list and test Hindsight with your data, visit