希望让 AI 代理远离其内容的出版商,应将内容放在付费墙后面,Bright Data 的 Jennifer Burns 对 TNW 表示。她说,任何人无需登录即可看到的内容都是公开的,也应向 AI 开放。付费墙算作一道屏障,Bright Data 不会触碰付费墙后的内容。
Publishers that want to keep AI agents away from their content should put it behind a, Bright Data’s Jennifer Burns told TNW. Anything a person can see withoutg in is public, she said, and should be open to AI too. A paywall counts as a, and Bright Data would not touch content behind one.
Burns 是 Bright Data 的高级公关与传播总监。该公司销售网络数据基础设施,即用于为 AI 模型、代理和市场研究收集公开网络数据的工具。她三年半前加入该公司,此前在地方新闻行业从事记者工作 20 年。
Burns is senior director of PR and communications at Bright Data. The company sells web data infrastructure, the tools that collect public web data for AI models, agents and market research. She joined three and a half years ago, after 20 years as a journalist in local news.
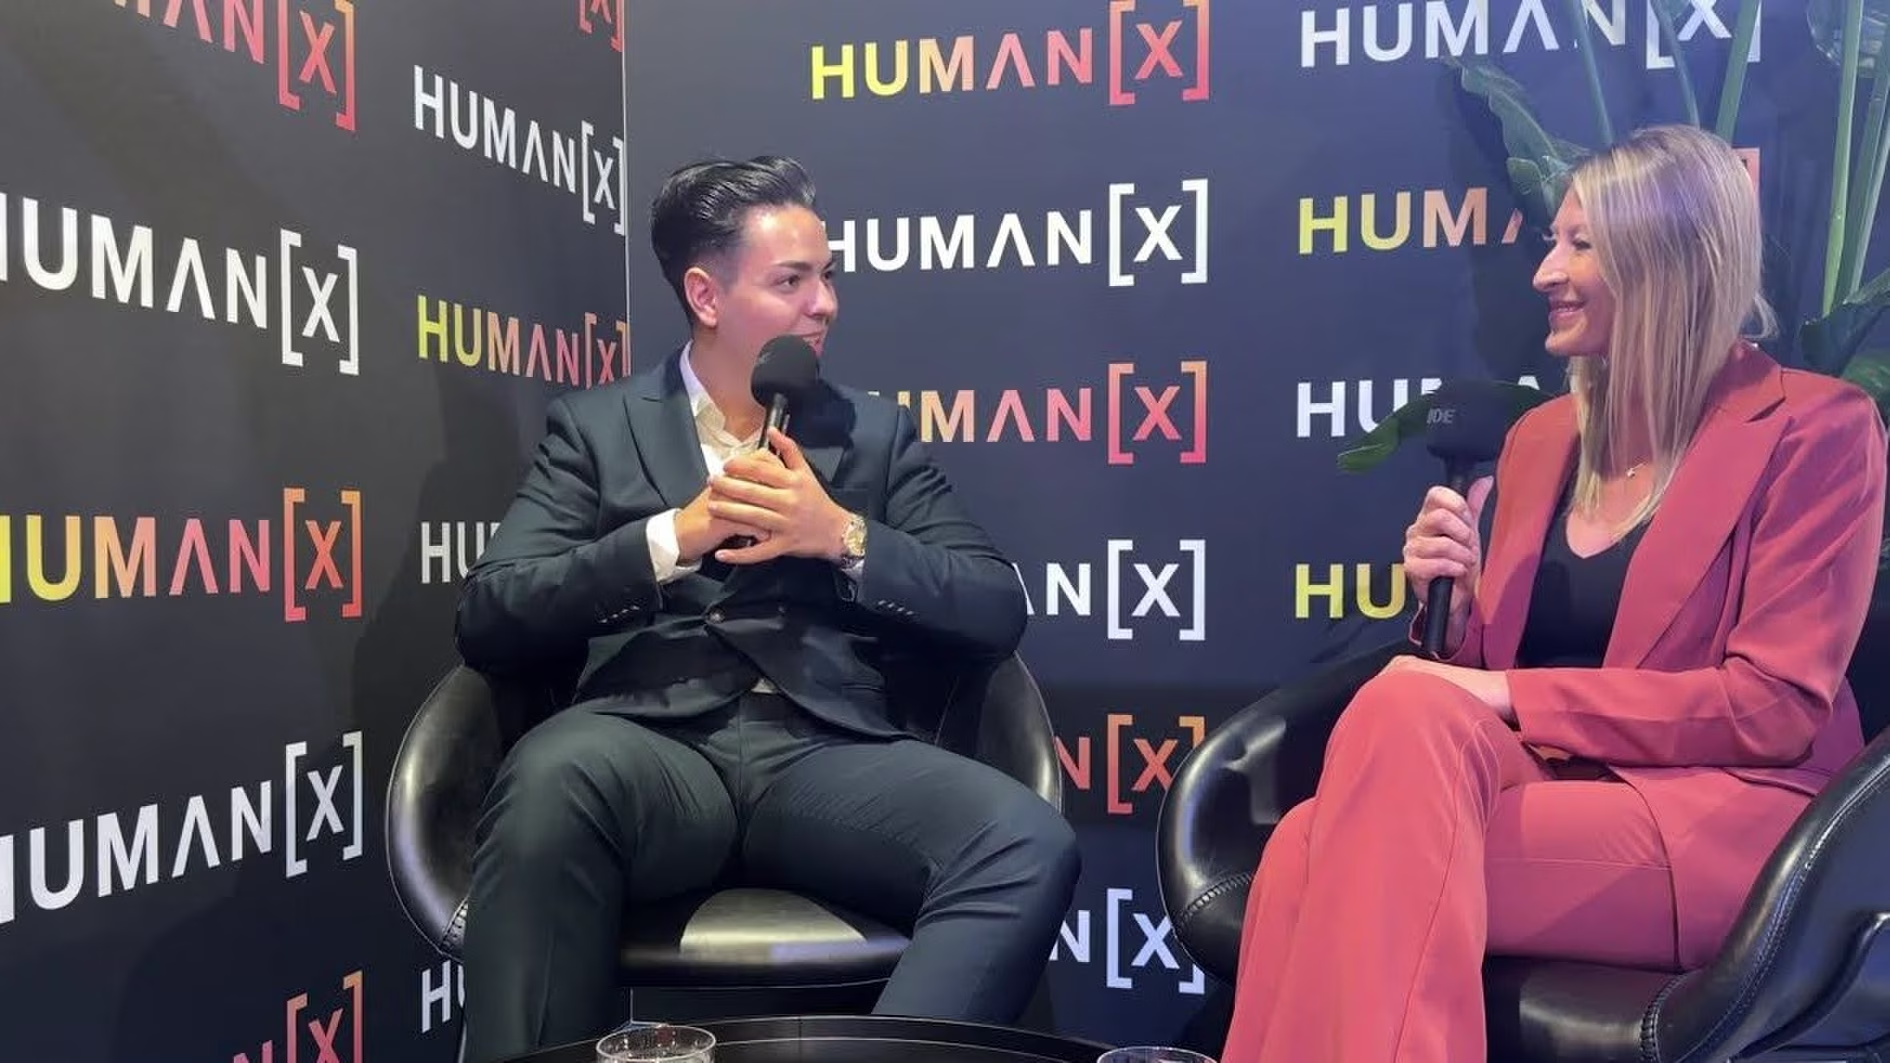
她在阿姆斯特丹的 HumanX 活动上接受了 TNW 播客主持人 Cristian Dina 的采访。早期节目曾邀请到 Atlassian 的 Avani Prabhakar 和 Remote 的 Job van der Voort。完整对话见下方视频。
She spoke to Cristian Dina at HumanX in Amsterdam for the TNW Podcast. Earlier episodes featured Atlassian’s Avani Prabhakar and Remote’s Job van der Voort. The full conversation is in the video below.
Burns 表示,公开意味着没有 Bright Data 的界限很清晰:付费墙后的数据不是公开的,其他一切都是。
Public means no Bright Data’s line is clear, Burns said. Data behind a is not public, and everything else is.
“如果你让任何人都能访问,那 AI 也应该能访问。在这一点上,你真的不能挑选谁能查看这些数据,以及查看的规模。”——Jennifer Burns,Bright Data Cristian 向她提出了出版商的观点:他们投入资金和资源创作内容,随后代理将其收集。她的回答依旧一致。不满代理的出版商可以将内容放在付费墙后,并自行决定谁能进入。
“If you make it accessible to any person, it should also be accessible to AI. There, you really can’t pick and choose who is going to be able to view that data and at what scale.”Jennifer Burns, Bright Data Cristian put the publishers’ case to her: they spend money and resources creating content, and then agents collect it. Her answer was the same. A publisher unhappy with agents can put its content behind a and choose who gets in.
“我认为这是一个真正的问题,市场仍需自行解决,但这不是由我们来决定会如何发展。”——Jennifer Burns同样的争议也在其他地方上演。Reddit 上周表示将要求用户登录。周一,《纽约时报》及另外三家美国报纸因抓取数据起诉了 Brave。
“I think that it’s a real issue and the market still has to work itself out, but that is not for us to decide how that’s going to happen.”Jennifer Burns The same fight is playing out elsewhere. Reddit said last week it will make users. On Monday, the New York Times and three other US papers sued Brave over scraping.
X 与 Meta 在法庭上对峙 Bright Data 曾因收集其数据而与 Meta 和 X 对簿公堂。Burns 表示,X 提起了诉讼,Bright Data 如同应对任何案件一样进行了抗辩。她说,法院已表明其行为合法。
X and Meta in court Bright Data has faced Meta and X in court over collecting their data. X brought its lawsuit, Burns said, and Bright Data fought it as it would any case. She said the courts have shown that what it does is legal.
“任何试图做的其他事情,如果不清楚地区分公共数据和非公共数据,都是一种守门行为。”Jennifer Burns 机器人从网络学习 Bright Data 现有 5 万客户,Burns 称,她加入时为 2 万。公司服务前 20 大 LLM 中的 14 家,每天处理 1 亿次智能体交互。员工从约 250 人增至约 600 人,公司最近聘任了新任 CTO。
“Anything else that you’re trying to do that does not make that clear distinction between public and non-public data is a form of gatekeeping.”Jennifer Burns Robots learning from the web Bright Data now has 50,000 customers, up from 20,000 when Burns joined, she said. It serves 14 of the top 20 LLMs and handles 100 million agent interactions a day. Staff numbers have grown from about 250 to around 600, and the company recently hired a new CTO.
Burns 称,2025 年底,机器人公司开始向 Bright Data 索要公共数据用于训练。一些公司想看人们如何拿起玻璃杯。他们需要不同尺寸的玻璃杯、阴影和家庭照明,以及不同的放置台面方式。她表示,拍摄所有这些内容需要花费漫长时间,但网络上已存在这些内容。
At the end of 2025, robotics companies started asking Bright Data for public data to train on, Burns said. Some wanted to see how people pick up a glass. They needed different glass sizes, shadows and home lighting, and different ways of placing it on a counter. Filming all of that would take forever, she said, but it already exists on the web.
2026 年初,公司大举进军上下文层。这是告诉智能体当前正在发生什么的实时数据,例如当前价格。她表示,没有它,LLM 或智能体的回答“基本没用”。
In early 2026, the company moved heavily into the context layer. That is live data that tells an agent what is happening now, such as current prices. Without it, an LLM or agent’s answer is “basically useless,” she said.
五个智能体和一个人类 Burns 在自己的工作中运行五个 AI 智能体。
Five agents and a human Burns runs five AI agents in her own job.
“并不意味着我变得不那么重要了。这让我更重要,因为我必须管理这些智能体。我不能让它们在没有人在回路的情况下运行。”Jennifer Burns 她表示,Bright Data 通过新闻计划免费向记者提供其工具。她希望更多记者快速采用 AI。她给 AI 公司的公关建议是:理解自己的故事,掌控它,并讲好它。公司里的每个人都应该能做到这一点。
“It doesn’t mean that I am less relevant. It makes me more relevant because I have to manage those agents. I can’t let them run without a human in the loop.”Jennifer Burns Bright Data gives its tools to journalists for free through a journalism programme, she said. She hopes more journalists take up AI quickly. Her advice to AI companies on PR is to understand their story, own it and explain it well. Everyone in the company should be able to do the same.
“不要为了 AI 而随意抛出‘AI’这个词。一切都是 AI。”Jennifer Burns
“Don’t throw around the word AI for the sake of AI. Everything is AI.”Jennifer Burns