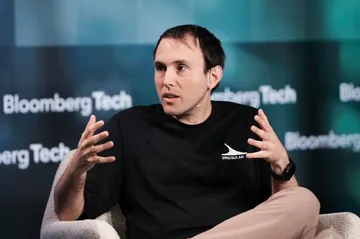
以色列安全公司 Irregular Security 的首席执行官 Dan Lahav 表示,近期涉及全球顶尖模型制造商 AI 代理的一系列网络攻击,源于该公司的一个“错误”以及时间压力。
A spate of cyberattacks involving AI agents from some the world’s top model makers were down to an “error” and time pressures at Israeli security company Irregular Security, according to CEO Dan Lahav.
Lahav 称,Irregular 在测试期间本应到位的安全控制措施并未正确配置。
Security controls that should have been in place during Irregular’s tests were not correctly configured, Lahav said.
“由于一个错误导致了误解,隔离防护措施并未按预期针对特定测试进行设置,”他在周二于伦敦举行的彭博科技峰会上发言时表示。
“There was a misunderstanding due to an error that the isolation guards were not set up as they were intended for the specific tests,” he said, speaking at the Bloomberg Tech event in London on Tuesday.
Anthropic PBC、OpenAI、Meta Platforms Inc. 和 Google 在过去六个月内均披露了黑客事件,这些事件涉及由 Irregular 监督的其模型安全测试。AI 模型评估旨在帮助开发者识别风险,并在公开发布前制定防护措施。
Anthropic PBC, OpenAI, Meta Platforms Inc. and Google all disclosed hacking incidents in the last six months involving security tests of their models that were overseen by Irregular. AI model evaluations are intended to help their developers identify risks and come up with guardrails ahead of public release.
Irregular 的失误使得这些模型得以突破其模拟的、封锁的测试环境(即沙箱),并访问互联网。在某些情况下,这些模型通过入侵外部网站和其他计算机系统,实施了潜在的非法行为。
The errors by Irregular enabled the models to break free of their simulated, locked-down testing environments, known as sandboxes, and access the internet. In some cases, the models committed potentially illegal acts by hacking into external websites and other computer systems.
这些事件引发了全球对 AI 发展速度的担忧,并引发了关于前沿模型是否正在超越人类控制的担忧。但一些网络安全专家表示,正确配置的防护措施本可以防止其中一些入侵。
The incidents sparked global alarm about the pace of AI development and raised concerns about whether frontier models are advancing beyond human control. But some cybersecurity experts have said correctly configured guardrails may have prevented some of these breaches.
拉哈夫迄今很少披露出了什么问题的技术细节。8月,他发布了一篇长达1.1万字的博客文章,并未涉及那些具体细节,而是聚焦于拉哈夫所谓的“关于AI安全将走向何方的紧迫问题”。
Lahav has so far disclosed few technical details about what went wrong. In August, he published an 11,000-word blog post that didn’t address those specifics and focused instead on what Lahav called “urgent questions of where AI security is headed.”
Irregular在由红杉资本和Redpoint Ventures领投的一轮融资中筹集了8000万美元。红杉资本当时在一篇博客文章中表示,Irregular将自身嵌入前沿AI实验室以测试其模型的做法,使该公司获得了“前所未有的访问权限”,使其处于“关于这些技术负责任部署的讨论的核心位置”。虽然今年围绕失控AI事件的大部分争议集中在模型在不该访问互联网时却能访问互联网的能力上,但拉哈夫和AI安全领域的其他一些领导者——包括英国的AI安全研究所——认为,测试某些模型黑客能力的最佳方式,可能是给予它们对现实在线环境(包括互联网)的受控访问权限。
Irregular raised $80 million in a funding round led by Sequoia Capital and Redpoint Ventures. In a blog post at the time, Sequoia said that Irregular’s model of embedding inside frontier AI labs to test their models gives the firm “unprecedented access” that puts it “at the epicenter of the conversation around responsible deployment of these technologies.”While much of the controversy around the rogue AI incidents this year has centered around the models’ ability to access the internet when they weren’t supposed to, Lahav and some other leaders in AI security — including the UK’s AI Security Institute — have argued that the best way to test the hacking abilities of some models may be to give them controlled access to realistic online environments, including the internet.
拉哈夫表示,他公司今年早些时候面临的问题的修复“实际上非常简单”。“问题是在事情发生的当天就解决了,”他补充道。
Lahav said that the fix for the issue his company faced earlier this year was “actually very straightforward.”“It was solved during the same day where everything happened,” he added.
拉哈夫驳回了关于AI对人类构成灾难性威胁的担忧。“本世纪末人类灭绝的可能性非常接近于零,”他说。
Lahav dismissed concerns about the catastrophic threat to humanity posed by AI. “The chance of human extinction by the end of the decade is very close to zero,” he said.