AI 实验室已将其声誉押注在模型基准测试上 — — 这是一种旨在衡量一个 AI 产品是否优于另一个 AI 产品的所谓中立且准确的评估系统。
AI labs have staked their reputations on model benchmarking — the supposedly neutral and accurate system of evaluations that are designed to measure whether one AI product is better than another.
然而,这些评估背后的方法复杂且仍在发展中,Irene Solaiman(Hugging Face 首席政策官)在上周 TechCrunch Disrupt 的一次讨论中表示。如果行业希望在未来依赖这些评估,测试需要汇聚成更一致的科学。考虑到这一点,我们能否信任目前正在发布的测试?
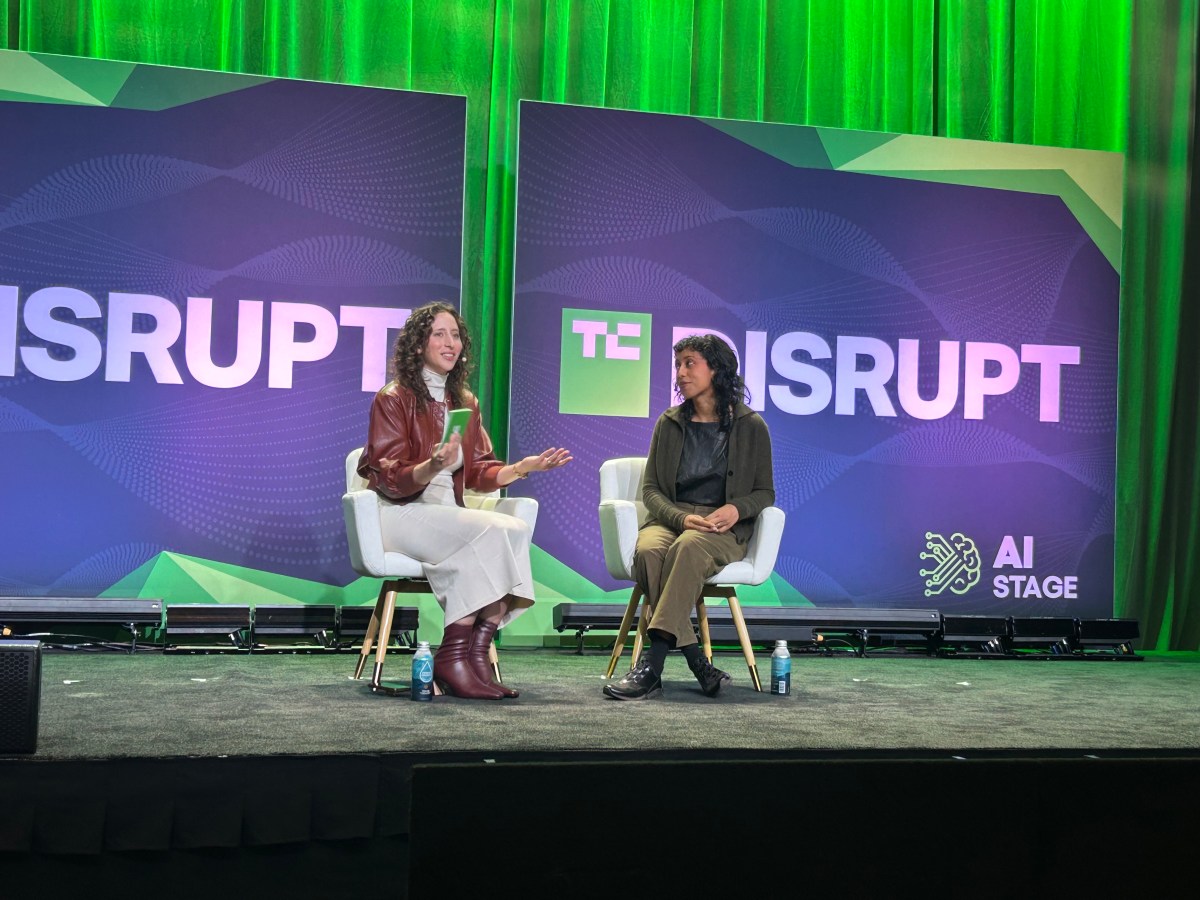
However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion at TechCrunch Disrupt last week. Testing needs to come together into a more consistent science if the industry is to rely on them in the future. With that in mind, can we trust the current tests that are being released?
“信任是一个意义重大的词,”Solaiman 说。“就我们是否能信任结果而言,其中一个重要部分是:你能否复现评估的结果?你是否具备对模型本身所需的访问程度 — — 这就是开放权重发挥重要作用的地方,”她补充道。
“Trust is such a weighted term,” said Solaiman. “In terms of whether we can trust results, one big part [of that] is can you reproduce the results of an evaluation? Do you have the level of access that you need to the model itself — this is where open weights come in in a big way,” she added.
模型评估的可重复性长期以来一直是基准测试中较为棘手的方面之一,并且仍然是行业内激烈争论的话题。
Reproducibility in model evaluations has long remained one of the stickier aspects of benchmarking — and remains a topic of significant debate in the industry.
除了单个测试的有效性之外,还存在一个额外的问题:该测试与其他评估相比如何。
Outside of an individual test’s validity, there’s also the added question of how that test compares to other evaluations.
“它们是一门正在发展的科学 — — 我们目前不知道如何对它们进行有意义的比较,”Solaiman 说。
“They are an evolving science — where we don’t know how to meaningfully compare them to each other,” Solaiman said.
“它们开始相对较快地变得无效,而且我们没有像所需那样蓬勃发展的生态系统,”她补充道。“目前存在对嵌入式评估生态系统的迫切需求,但决定谁在什么任务上是有效评估者的资格标准亟需更多标准化。”嵌入式评估者的概念 — — 即所谓的“中立”第三方观察者被置于 AI 组织内部 — — 在过去几个月里逐渐流行起来,因为 AI 实验室正在应对一系列安全事件,这些事件引发了人们对其技术潜在危害的担忧。Hugging Face 曾因其中一起事件而广受关注。
“They start to get ineffective relatively quickly, and we don’t have as much of a thriving ecosystem as we need,” she added. “There’s this hunger for an embedded evaluator ecosystem now, but the qualifications that determine who is an effective evaluator across what tasks need a lot more standardization.”The idea of embedded evaluators — in which supposedly “neutral” third-party observers are placed inside AI organizations — has been popularized over the last several months, as AI labs grapple with a rash of safety incidents that have spurred concerns over the potential harms of their technology. Hugging Face was famously the target of one of those incidents.
与其依赖政府主动监管来识别和缓解模型安全问题,实验室更倾向于推动第三方解决方案。然而,这些评估者究竟有多中立或有效仍存在疑问。Anthropic 决定聘请埃森哲作为其首个评估者,引发了不少批评,一些评论者嘲讽该咨询公司具备完成此任务的资格。
Instead of active government regulation to identify and mitigate model safety concerns, labs have pushed for the third-party solution. However, doubts remain over how neutral or effective those evaluators will actually be. Anthropic’s decision to hire Accenture as its first evaluator spurred a good amount of backlash, with some critics mocking the idea that the consulting firm was qualified to do the task at hand.
如今,评估工作已从仅测试模型本身,转向测试模型周围的整个系统 — — 包括套件(harness)和代理(agent)。套件 — — 即用户用来访问模型的工具 — — 具体来说,对模型的性能有很大影响,一个性能较弱但套件更好的模型,完全可能轻松超越前沿模型,Soleiman 如此分享。
Evaluations are now moving from merely a test of the model itself to a test of the entire system around the model — including the harness and agent. The harness — or the tool the user is using to access the model — specifically, has a lot to do with a model’s performance, and a weaker model with a better harness could easily out perform a frontier model, Soleiman shared.
“代理评估真的很难,而且成本很高,”Solaiman 说。“我们现在对模型有更多的评估。……我们对套件的评估较少,我们正在为整体代理开发更好的评估方法 — — 因为很多人正是从中获得价值,”她补充道。
“Agentic evals are really hard and really expensive,” said Solaiman. “We have just more evaluations for models. … We don’t have as many evaluations for harnesses, and we are developing better evaluations for the holistic agent — because that’s what a lot of folks are getting value out of,” she added.
换句话说:目前评估领域略显混乱,若基准测试仍被视为行业领袖的有用工具,那么一种更统一、行业范围内的方法 — — 即让所有人站在同一页面上 — — 可能是必要的。
In other words: the evaluation space is a bit of a free-for-all at the moment, and if benchmarking is going to continue to be seen as a useful tool for industry leaders, a more uniform, industry-wide approach — where everyone is on the same page — may be necessary.