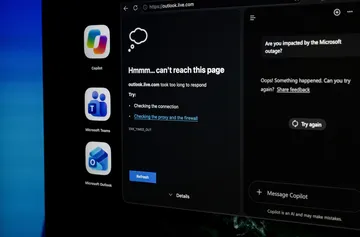
上周导致微软公司生产力软件瘫痪的漏洞,自七月起就在公司数据中心潜伏而未被发现。
The bug that crippled Microsoft Corp. productivity software last week had been lurking undetected in the company’s data centers since July.
当软件制造商在11月11日对用户流量进行例行重新路由时,系统出现故障。随后,关键的Outlook、Teams、Copilot AI 助手以及其他若干服务的服务器开始失效,最终导致全球用户遭遇中断。
When the software maker did some routine rerouting of user traffic on Nov. 11, the system malfunctioned. Then servers critical to Outlook, Teams, the Copilot AI assistant and several other services, began to fail — ultimately triggering outages for people around the world.
根据公司周日向客户发布的初步报告,微软几乎没有意识到问题已经酝酿约15小时。随后,微软又花费了15小时来识别并开始推送修复——对高度依赖该公司软件的有线世界而言,这是一段漫长的时间。
Microsoft had little inkling it had a problem brewing for about 15 hours, according to a preliminary report the company issued to customers on Sunday. Microsoft then spent another 15 hours identifying and starting to roll out the fix — an eternity for a wired world that relies heavily on the company’s software.
11月11日纽约时间晚上8点左右,Teams 视频会议和聊天服务的流量被自动重新路由到同样处理 Outlook 流量的独立服务器系统。再加上本周早些时候因无关问题导致的服务器容量损失,触发了该漏洞,使服务器在流量意外激增后耗尽内存。
Just after 8 p.m. New York time on Nov. 11, traffic from the Teams videoconference and chat service was automatically rerouted to the separate system of servers that also handle Outlook traffic. That, combined with a loss of server capacity caused by an unrelated issue earlier in the week, triggered the bug, which prompted servers to exhaust their memory after an unexpected surge in traffic.
服务器开始失效。自动化系统将电子邮件和用户流量重新路由到微软系统认为是其他健康服务器的地方,进一步加剧了问题,使漏洞也出现在这些服务器上。到11月12日上午11点30分——正值美国业务流量高峰时段——微软意识到出现了问题。
Servers began to fail. The problem was worsened by automated systems that rerouted emails and user traffic to what Microsoft’s system thought were other, healthy servers, causing the bug to show up there, too. By 11:30 a.m. on Nov. 12 – just as traffic from business in the US was reaching its peak – Microsoft realized it had a problem.
公司又用了15小时的故障排查,才开始部署针对该问题的修复。在此期间,微软的众多企业和政府客户的工作几乎停滞,电子邮件收件箱无法加载,Teams 邀请消失,员工只能改打电话或使用纸笔。
It took the company another 15 hours of troubleshooting to start deploying a fix for the issue. In the meantime, work at many of Microsoft’s corporate and government clients ground to a halt, as email inboxes failed to load, Teams invitations went missing and workers resorted to phone calls and pen and paper.
这次宕机令微软感到尴尬,也提醒人们,过度依赖单一技术供应商存在风险。负责微软工作场所软件的公司执行副总裁查尔斯·拉曼纳,周一早些时候在X社交媒体平台上发帖,就宕机事件道歉,帖子详细说明了出了什么问题。
The outage was an embarrassment for Microsoft, and a reminder of the risks of relying so heavily on a single technology vendor. Charles Lamanna, the Microsoft executive vice president who oversees the company’s workplace software, apologized early Monday for the outage in a post on the X social media site that offered more detail on what went wrong.
一份更全面的时间表,包含在面向使用微软365软件套件的技术人员的更新中,显示了该公司自动化的软件运行维护工作如何帮助引发了连锁故障。周四达到最低点时,支撑Outlook的服务器中,超过80%没有响应。
A more comprehensive timeline, included in an update for technologists who use the Microsoft 365 bundle of software, showed how the company’s automated efforts to keep its software running helped spark a cascading failure. At the nadir on Thursday, more than 80% of the servers behind Outlook were unresponsive.
此类宕机通常最多持续几个小时。但这次持续时间更长,因为服务器一旦恢复服务,就会被等待的流量淹没,再次失效。而且,由于该错误数月来未被发现,通过回滚最近更新来稳定系统的努力也没有效果。
Such outages often last just a few hours at most. In this case, it took longer because as soon as servers returned to service, they were overwhelmed by waiting traffic and failed again. And because the bug had gone unnoticed for months, efforts to stabilize the system by rolling back recent updates had no effect.
微软在广泛部署前,会在实验室和网络的小部分上测试对其网络的更改,这是支持大型在线服务的公司的标准流程。
Microsoft tests changes to its network in labs and on small portions of its network before deploying them widely, standard protocol for companies that support large online services.
拉曼纳表示,这个错误没有被发现,是因为公司实验室中的模拟流量模式和硬件,没有反映服务器后来遇到的真实世界条件。微软的测试通常侧重于较旧、较弱的系统,以评估更新是否会绊倒公司云端中最薄弱的环节。导致服务器瘫痪的错误,在拥有更多处理能力的较新硬件上更具破坏性。
This bug wasn’t caught, Lamanna said, because the simulated traffic patterns and hardware in the company’s labs didn’t reflect the real-world conditions the servers later encountered. Microsoft’s testing typically focuses on older and weaker systems to assess whether updates will trip up the weakest link in the company’s cloud. The bug that caused servers to seize up is more destructive on newer hardware with more processing power.